Responded16 / 22 checks passed
Remote MCP server to run your Atako AI agents: chat, projects, files, integrations and channels.
- Passed: Handshake
- Passed: Tools listed
- Passed: Updated recently
Median latency 132 ms · Last checked
Explore
Evidence for your next connection.
Independent measurements of remote MCP servers. Every observation has a timestamp.
Read-only probesMCP server · Code & DevOps
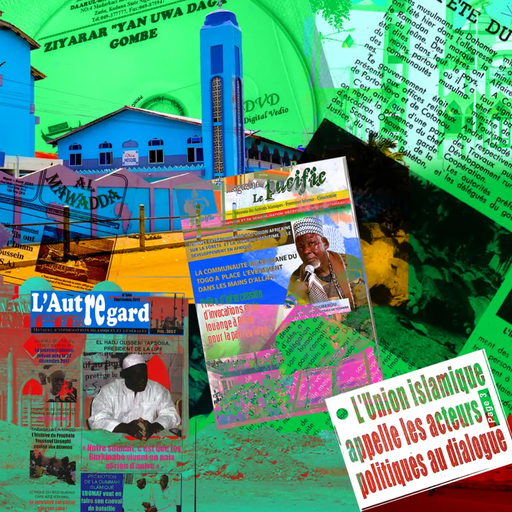
Read-only access to the Islam West Africa Collection via Hugging Face datasets.
1 failed · 7 not measured
Median of successful probes over 7 days
Share of countable probes over 30 days, including daily rollups. Auth challenges are excluded.
Tool definitions returned by this server
Independent monitoring
Responded
The server completed its last measured handshake. This is an observation, not a guarantee.
Last checked| Test area | Passed | Failed | Unmeasured |
|---|---|---|---|
ConnectionCan a client connect and discover tools? | 5 | 0 | 0 |
Reliability & speedDoes it respond consistently and quickly? | 1 | 0 | 3 |
Access & authenticationWhat is required to use this server? | 1 | 0 | 2 |
Tool qualityAre the tool definitions usable by an agent? | 3 | 1 | 0 |
Publisher identityCan the publisher be traced to its source? | 4 | 0 | 2 |
Unmeasured means there is not enough evidence to decide. How these checks work
Start using Islam West Africa Collection (IWAC)
Choose your client, copy the configuration, then enable the server in your client’s MCP settings.
Run this command in your terminal, then restart Claude Code.
Claude Code
claude mcp add --transport http islam-west-africa-collection-iwac https://islam.zmo.de/mcp/Capabilities
Selection workbench: items, concordance, coverage, compare (requires comparison), attention, aliases, or paginated manifest/CSL-JSON/BibTeX exports. Exact filters intersect. limit/offset also page compare/coverage/attention cells. Coverage measures archive availability. Exports identify this page and dataset snapshot; compare snapshot IDs across pages. Schema discovery: iwac://datasets/{subset}.
DiscoveredRetrieve the full text and metadata of one IWAC item by an id returned from `search` (format '<category>:<number>', e.g. 'articles:28576'). Returns {id, title, text, url, metadata}: `text` is the item's OCR / abstract / transcription / description, `url` is the canonical islam.zmo.de link to cite, and `metadata` holds the remaining fields (author, date, country, newspaper, AI sentiment, …). Categories: articles, publications, references, documents, index, audiovisual, images.
DiscoveredGet one article (by id): full metadata, the AI abstract (description_ai), AI sentiment, and OCR text, in 25k-char parts (follow `next_offset`). Pass a `keyword` to get ~2000-char excerpts around each match instead.
DiscoveredGet one audiovisual record by id: full description and transcription (where one exists), creator/publishing channel, duration, medium, subjects, places, language, rights, source, and three distinct links: `url` (the IWAC page, the one to cite), `external_url` (where a harvested video plays) and `media_url` (a deposited file). `source_type` says which to expect. A long transcription comes in 25k-char parts (follow `next_offset`); `keyword` returns excerpts instead.
DiscoveredOverall statistics for every IWAC subset, including `fulltext_coverage` — how many items in each subset actually carry searchable full text in this dataset. Read that before treating any keyword count as a full-text census.
DiscoveredCount pairs of metadata values co-tagged on the same items. Matrix/network views show descriptive associations, not causal links. Filters apply before pair counting; top_n caps the vocabulary.
DiscoveredCompare article counts, newspaper counts, date ranges, and claude-haiku-5-5 polarity across countries.
DiscoveredGet one archival document (by id): full metadata, AI description, and OCR text, in 25k-char parts (follow `next_offset`). Pass a `keyword` to get ~2000-char excerpts around each match instead, useful for long documents.
DiscoveredRank exact metadata values, splitting pipe-separated tags. Reports missing metadata and optional coverage over time. Choose spatial for mentioned places, country for stored country tags, or subject/author/language.
DiscoveredGet one photograph by id: title, photographer, capture date, place and coordinates, subjects, rights, the IIIF manifest, and the full-resolution `image_url`. The server returns URLs, not image bytes.
DiscoveredGet full details of an index entry by id (raw dataset columns, French names — Titre, Prénom, Coordonnées…).
DiscoveredText length, lexical richness and readability by country/newspaper/year. Metrics are precomputed; readability is French-specific and excludes other languages. Missing values are disclosed. Compare distributions as descriptive evidence.
DiscoveredPer-newspaper article counts and date ranges.
DiscoveredPlace tags joined to authority coordinates. Separates publication countries from mentioned places; missing geocodes are counted explicitly.
DiscoveredFull OCR text of a publication in 25k-char parts (follow `next_offset`), or ~2000-char excerpts around keyword matches (accent-insensitive; capped: see match_count vs excerpts_returned).
DiscoveredFull bibliographic record for one academic reference (by id), including the complete abstract (present for ~51% of references), subjects, DOI/URL, and host-work details (book, volume, issue, pages).
DiscoveredStable-hash sample of matching stored embeddings, projected with PCA. Reports eligible, invalid, missing and capped counts, seed and explained variance. Group counts describe the sample. Coordinates are chart-only; this is not the published UMAP landscape. Needs no API key.
DiscoveredAggregate AI labels over a shared selection. model:"all" compares independent annotators and their coverage; model:"consensus" reads the stored panel majority. Choose compare_models and agreement_field for pairwise Cohen's kappa and quadratic weighted kappa, with explicit denominators. Labels are interpretations, not ground truth; subjectivity is weak evidence and its caveat must accompany findings.
DiscoveredNearest stored embeddings by cosine similarity. Articles and documents lead with the dataset's published top 10. Scores run high (unrelated ~0.7) and rank reading candidates; >= 0.97 suggests a near-duplicate, but no threshold proves a reprint. Returns source IDs and dates. Corpus-wide candidate generation belongs offline.
DiscoveredCounts by Gregorian or Hijri year/month, or pooled lunar month. Group by country/newspaper. Partial dates and missing lunar dates are disclosed. normalize_by returns numerator counts and per-bucket denominators in the same country/outlet/date scope, removing thematic filters. Shares describe IWAC holdings.
DiscoveredCounts of offline LDA topic assignments, optionally over time. Topic labels are interpretive model outputs; exact topic_id filters select assignments rather than keyword matches. Reports unclassified coverage.
DiscoveredList audiovisual materials, newest first (francophone web video from Burkina Faso, Togo and Benin; deposited Nigerian Hausa/Arabic recordings). Filter by country, publishing channel or `source_type`.
DiscoveredList lieux from the IWAC index, sorted by frequency (most-referenced first). The optional 'country' filter selects entries that APPEAR IN records from that country (mentioned-in, not located-in), ranked by collection-wide 'frequency' — so foreign and cross-border entries can appear. Nigeria reaches only the few entries its references mention (index frequency counts articles, publications and references; no article is Nigerian).
DiscoveredList the Islamic periodical/series titles in the publications subset, with issue counts and year ranges. Use the returned newspaper value as the `newspaper` filter on search_publications.
DiscoveredList personnes from the IWAC index, sorted by frequency (most-referenced first). The optional 'country' filter selects entries that APPEAR IN records from that country (mentioned-in, not located-in), ranked by collection-wide 'frequency' — so foreign and cross-border entries can appear. Nigeria reaches only the few entries its references mention (index frequency counts articles, publications and references; no article is Nigerian).
DiscoveredList sujets from the IWAC index, sorted by frequency (most-referenced first).
DiscoveredSearch the Islam West Africa Collection across newspaper articles, Islamic publications, archival documents, academic references, audiovisual recordings, photographs, and the authority index (persons/places/organisations/events/subjects). Pass ONE concept or name — e.g. 'Tijaniyya', 'laïcité', 'Sheikh Gumi', 'pèlerinage'. Matching is accent- and case-insensitive; a multi-word query requires every word to appear somewhere in the item, so prefer a single concept per call. Write query strings and concept keywords in French for press/publication/document/index discovery even when the user's report language is not French. Academic references are multilingual, so try French and English title/abstract terms when relevant; metadata/filter labels remain French. Use the French transliteration of Islamic terms (Tabaski not 'Eid al-Adha', charia not 'sharia', Maouloud not 'Mawlid'). Returns {results:[{id,title,url,category}], ranking}; each result's `category` names its subset and the `ranking` field documents the ordering. Pass an id to `fetch` to read the full text. For filtered queries (by country, date, or newspaper) use the search_* tools instead.
DiscoveredSearch IWAC newspaper articles by keyword (title + OCR + AI abstracts, French and English), country, newspaper, subject, and date range. Use French concept keywords regardless of the user's report language. Matching is accent- and case-insensitive.
DiscoveredSearch audiovisual materials by keyword and metadata: francophone web video from Burkina Faso, Togo and Benin (TV reports, association and campus recordings), plus deposited Nigerian Hausa/Arabic recordings. Keyword matches title, creator, publisher, subject, spatial, language, source, the item's own description (the richest text most of these items have) and its transcription where one exists. Each row says which population it is from (`source_type`) and carries either `external_url` (a video to watch) or `media_url` (a file), never both.
DiscoveredFilter articles by claude-haiku-5-5 sentiment labels (accent/case-insensitive exact match). One model's reading, not a consensus — 5 other models scored the same articles and often disagree; get_sentiment_distribution with model:"all" shows by how much. `subjectivity` is much the weakest of the three scales, so treat a set selected on it as a lead to read rather than as a finding.
DiscoveredSearch the small archival-documents subset (~26 items: Islamic association reports, flyers, project documents — mostly Burkina Faso). Use French concept keywords regardless of the user's report language. Most have OCR text and an AI description. Call with no arguments to list all.
DiscoveredSearch the IWAC photographs (30 items: mosques, radio stations, schools, signage and street scenes documented during fieldwork). Keyword matches title, creator, subject, place and the rare caption. Each result carries `image_url` (the full-resolution file), `coordinates` ('lat, lng' where known) and the canonical IWAC page. Call with no arguments to list all. Captions are almost never present, so prefer subject/place filters over keywords, or semantic_search_images when it is enabled.
DiscoveredSearch the IWAC authority index (persons, places, organisations, events, subjects) by name. Accent/case-insensitive.
DiscoveredSearch Islamic publications (periodical issues, books). `keyword` matches title, subject, table of contents, and full OCR text (TOC hits come back as matching_toc_entries); use French concept keywords regardless of the user's report language. Filter by newspaper/series, subject, country and year. Use list_periodicals to discover series titles, and get_publication_fulltext for keyword excerpts from a single issue.
DiscoveredSearch academic references (journal articles, book chapters, theses, books, reports) by keyword and metadata. `keyword` requires every word in the title + abstract ("quote" a phrase). References are multilingual: try French and English title/abstract keywords when relevant; metadata/filter values such as `reference_type` and `language` use French labels. Results include a short abstract snippet — use get_reference for the full abstract and bibliographic detail.
DiscoveredSemantic search over article title + full text, including articles whose OCR is not public. Query in any language. Runs the corpus model, EmbeddingGemma 2, locally with no API key (first use downloads ~350 MB). similarity_score only ranks within one query.
DiscoveredFind photographs by describing what they SHOW, in any language ('mosquée en construction', 'street signage in Arabic'). This is cross-modal: the ranking runs against a multimodal embedding of the photograph itself, not against a caption, so it works even though only 2 of the 30 images have one. Runs the corpus model, EmbeddingGemma 2, locally with no API key (first use downloads ~350 MB). similarity_score only ranks within one query.
DiscoveredSemantic search over publication tables of contents, present for ~40% of issues (none for An-Nasr Vendredi, 130 of 695 Islam Info issues): use search_publications for the rest. Rows show the first 600 characters of each table. Query in any language. Runs the corpus model, EmbeddingGemma 2, locally with no API key (first use downloads ~350 MB). similarity_score only ranks within one query.
DiscoveredSemantic search over academic references by title + abstract, across languages. Only references with an abstract (about half) are covered; use search_references for the rest. Runs the corpus model, EmbeddingGemma 2, locally with no API key (first use downloads ~350 MB). similarity_score only ranks within one query.
DiscoveredRecent measurements
| Checked | Result | Response | Tools |
|---|---|---|---|
| Connected | 119 ms | 39 | |
| Connected | 129 ms | 39 |